-
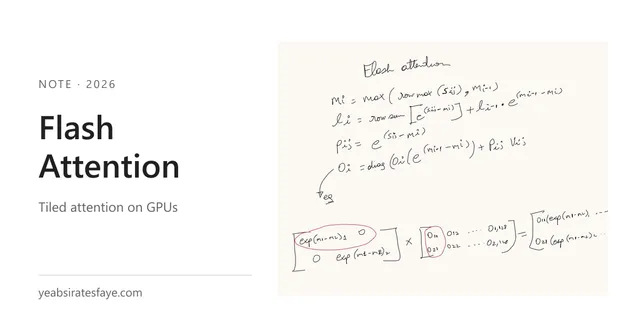
Flash Attention Notes #papers#llm#gpu A first-principles walkthrough of tiled attention, online softmax, and GPU memory movement.
-
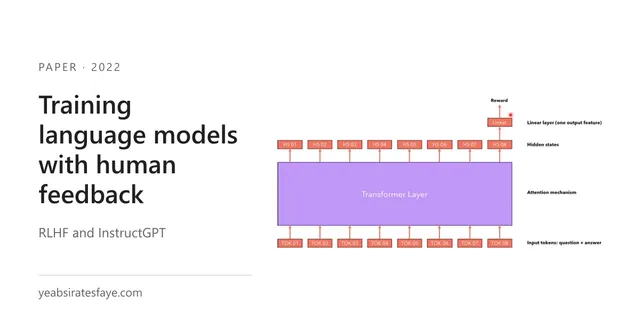
Training Language Models to Follow Instructions with Human Feedback Notes #papers#llm#alignment A review of the InstructGPT paper covering supervised fine-tuning, reward modeling, and PPO with human feedback.
-
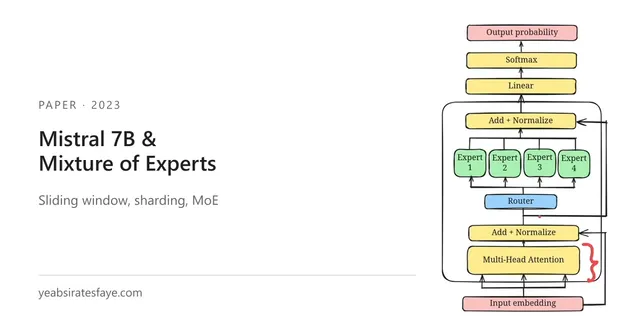
Mistral 7B & Mixture of experts(8x7B) Notes #papers#llm Sliding window attention, rolling buffer cache, model sharding, and mixture of experts from dense to sparse.
-
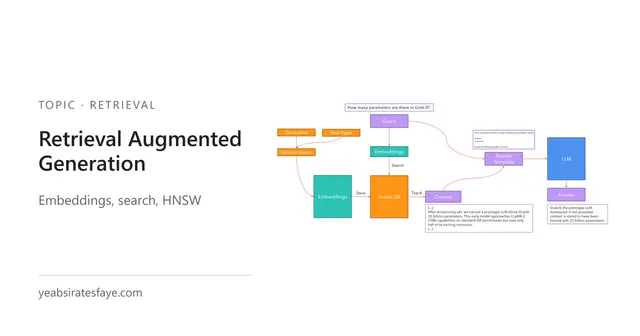
Retrieval Augmented Generation (RAG) Notes #llm#retrieval How RAG works from first principles: chunking and embeddings, Sentence-BERT similarity, and HNSW vector search.
-
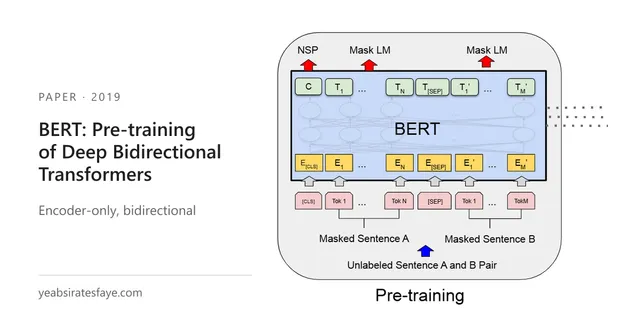
BERT: Pre-training of Deep Bidirectional Transformers Notes #papers#llm Review of the 2019 BERT paper, covering masked language modeling, next sentence prediction, and the encoder-only stack.
-
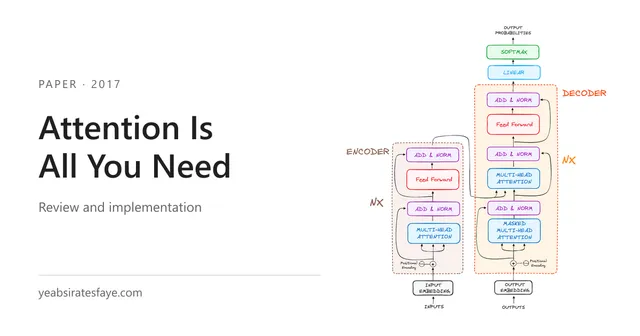
Attention is All You need Notes #papers#llm Review and implementation of the 2017 transformers paper.
-
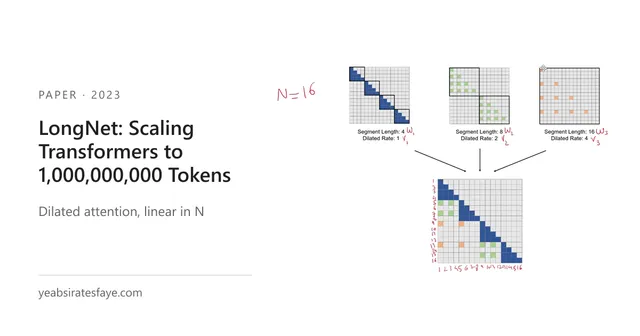
LongNet: Scaling Transformers to 1,000,000,000 Tokens Notes #papers#llm Review of the 2023 LongNet paper and its dilated attention.
-
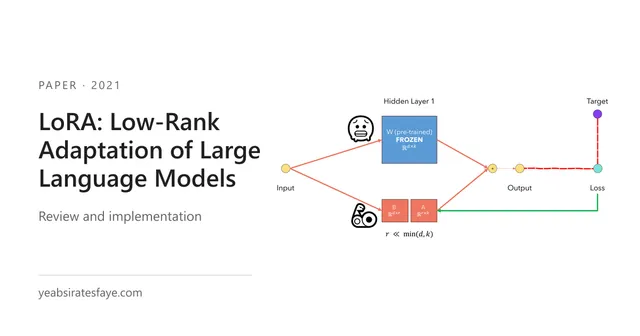
LoRA: Low-Rank Adaptation of Large Language Models Notes #papers#llm Review and implementation of the 2021 LoRA paper.