-
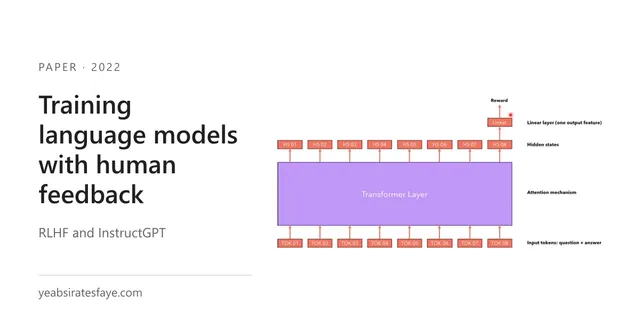
Training Language Models to Follow Instructions with Human Feedback Notes #papers#llm#alignment A review of the InstructGPT paper covering supervised fine-tuning, reward modeling, and PPO with human feedback.
A review of the InstructGPT paper covering supervised fine-tuning, reward modeling, and PPO with human feedback.